All Blogs

How do CUDA Kernels work?
A CUDA Kernel is a function that runs on the GPU and is executed by many threads at the same time, where each thread finds and does its own small part of the work.
The Future of Software Development
The Future of Software Development is a world where AI models become so smart, so fast, and so cheap that we simply tell the computer what we want, and AI agents build, test, and ship it for us. The work of software engineers moves from writing every line of code to building, checking, and improving the systems around these AI models.
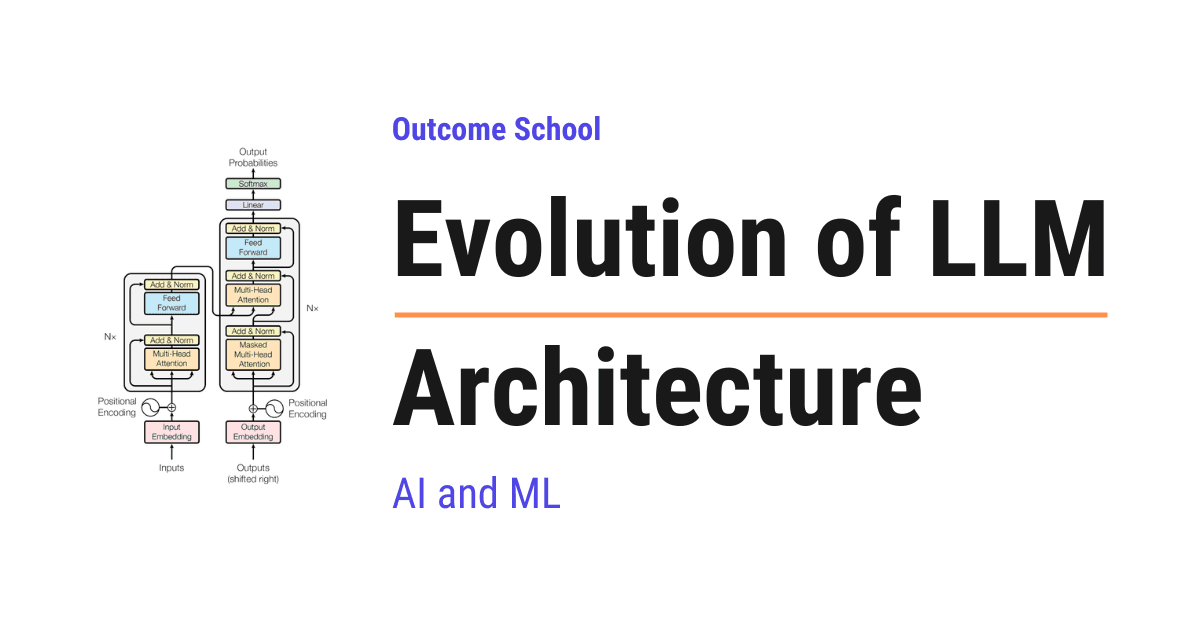
Evolution of LLM Architecture
LLM architecture evolved from RNNs that read one word at a time, to Attention, to the Transformer, to scaling, and to Mixture of Experts (MoE) that we use today.
How do Top-k and Top-p Sampling work?
Top-k Sampling keeps a fixed number of the most likely tokens, and Top-p Sampling keeps the top tokens whose total probability reaches p. The LLM picks from them.
Jev and System One Models Explained
Jev is a System One Model, a new kind of AI model that does not write text. It only makes fast decisions, with a confidence score, that our software can use directly.
Design a Real-Time Voice AI Agent
A Real-Time Voice AI Agent listens to us, understands, thinks, takes actions, and talks back in a natural voice within a fraction of a second. Let's design one.
How does Temperature control LLM output?
Temperature is a single number that controls how an LLM picks the next token. Low Temperature gives safe, predictable answers, and high gives creative ones.
What is Recursive Self-Improvement (RSI)?
Recursive Self-Improvement (RSI) is when an AI system improves its own abilities, and then the improved version improves itself further, again and again.
What is N-gram Speculation in LLMs and How Does It Speed Up Generation?
N-gram Speculation makes an LLM write faster by guessing the next few tokens from matching text it has already seen, and then verifying them in one run.