What Are L1 and L2 Loss Functions?
- Authors
- Name
- Amit Shekhar
- Published on


L1 and L2 are two loss functions in machine learning used to minimize the error. L1 Loss is the Least Absolute Deviations, and L2 Loss is the Least Square Errors. L2 is preferred in most cases, but L1 works better when there are outliers.
In this blog, we will learn about the L1 and L2 Loss functions.
I am Amit Shekhar, Founder @ Outcome School, I have taught and mentored many developers, and their efforts landed them high-paying tech jobs, helped many tech companies in solving their unique problems, and created many open-source libraries being used by top companies. I am passionate about sharing knowledge through open-source, blogs, and videos.
I teach AI and Machine Learning at Outcome School.
Let's get started.
L1 vs L2 Loss Function
L1and L2 are two loss functions in machine learning which are used to minimize the error.
L1 Loss function stands for Least Absolute Deviations. Also known as LAD.
L2 Loss function stands for Least Square Errors. Also known as LS.
L1 Loss Function
L1 Loss Function is used to minimize the error which is the sum of the all the absolute differences between the true value and the predicted value.

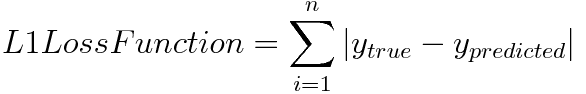
L2 Loss Function
L2 Loss Function is used to minimize the error which is the sum of the all the squared differences between the true value and the predicted value.

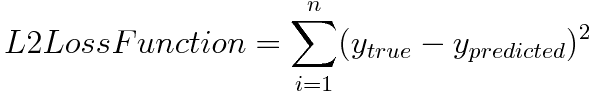
A quick note for you
No matter which tech domain you work in, get familiar with these topics:
- LLM
- RAG
- MCP
- Agent
- Fine-tuning
- Quantization
We put it all together in one video:
AI Engineering Explained: LLM, RAG, MCP, Agent, Fine-Tuning, and Quantization
No need to stop reading - bookmark it and watch later when you get time. Future you will thank you.
Now, let's get back to the topic.
How to decide between L1 and L2 Loss Function?
Generally, L2 Loss Function is preferred in most of the cases. But when the outliers are present in the dataset, then the L2 Loss Function does not perform well. The reason behind this bad performance is that if the dataset is having outliers, then because of the consideration of the squared differences, it leads to the much larger error. Hence, L2 Loss Function is not useful here. Prefer L1 Loss Function as it is not affected by the outliers or remove the outliers and then use L2 Loss Function.
Watch the video format: L1 and L2 Loss Functions in Machine Learning
Stay updated: Subscribe to our newsletter to get our latest AI and Machine Learning blogs straight to your inbox.
Frequently Asked Questions
What are the other names of L1 and L2 Loss Functions?
L1 Loss Function stands for Least Absolute Deviations, also known as LAD. L2 Loss Function stands for Least Square Errors, also known as LS. Both are loss functions in machine learning that are used to minimize the error.
Is L1 Loss Function affected by outliers?
No. L1 Loss Function is not affected by the outliers. This is why we prefer L1 Loss Function when outliers are present in the dataset. L2 Loss Function does not perform well in that case.
Why do outliers hurt L2 Loss Function?
L2 Loss Function uses the squared differences between the true value and the predicted value. When the dataset has outliers, squaring their differences leads to a much larger error. This is why L2 Loss Function does not perform well with outliers.
Can we still use L2 Loss Function if the dataset has outliers?
Yes. We can remove the outliers first and then use L2 Loss Function. Removing them avoids the much larger error that their squared differences would cause. The other option is to prefer L1 Loss Function, as it is not affected by the outliers.
That's it for now.
Thanks
Amit Shekhar
Founder @ Outcome School
You can connect with me on:
Follow Outcome School on: