All Blogs

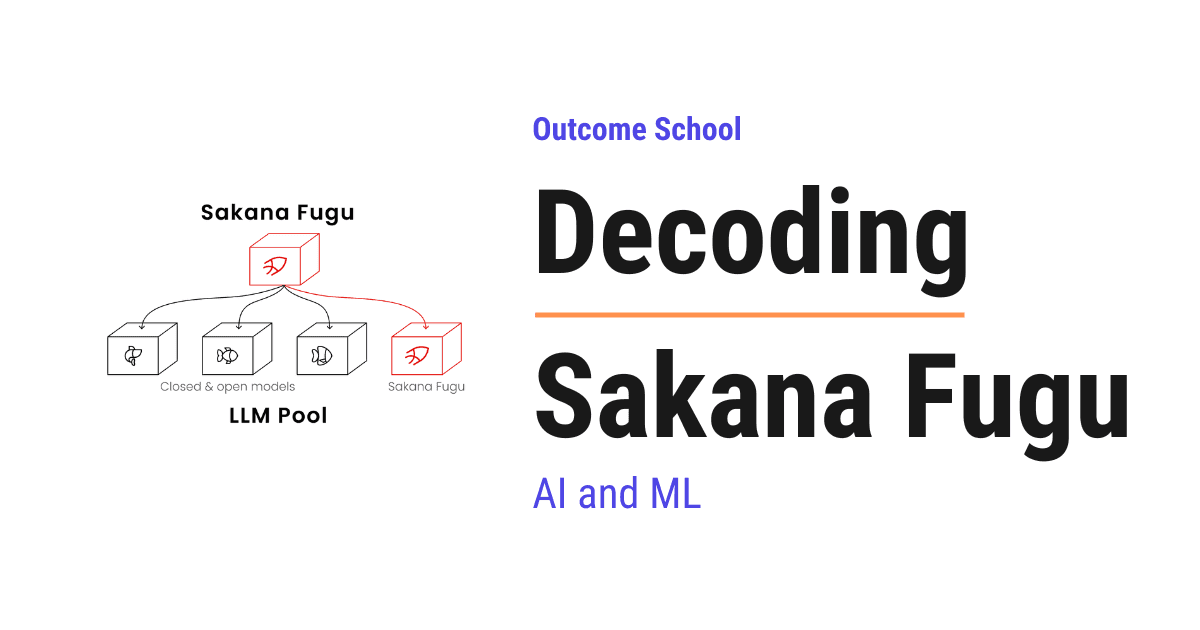
What is Sakana Fugu? The Technical Report Explained
Sakana Fugu is a family of AI models that work like a conductor. They decide which other AI models should work on our question and combine their answers.
How do Diffusion Language Models (DLMs) work?
A Diffusion Language Model writes text by starting from pure gibberish and cleaning it up again and again, instead of writing one word at a time from left to right.
How does an Embedding Cache work?
An Embedding Cache stores the embeddings we have already computed, so that we reuse them for the same text instead of computing them again. It saves money and time.
How do World Models work?
A World Model is an AI that learns an internal copy of how an environment behaves, so that it can predict what happens next when an action is taken.
How does vLLM work?
vLLM is a high-throughput engine for serving LLMs. It uses PagedAttention to manage the KV cache memory efficiently, so it can serve many more users at once.
LLM Inference Optimization
LLM Inference Optimization is the set of techniques, like KV Cache, Flash Attention, and Continuous Batching, that make LLMs fast and scalable in production.
How does Function Calling work in LLMs?
Function Calling lets an LLM use external tools and APIs. The model does not run the function itself. It tells our code which function to call and with what inputs.
How does GGUF work?
GGUF is a single file format that stores everything needed to run an LLM locally, like the weights, the tokenizer, and the settings, all in one file.
How does Knowledge Distillation work?
Knowledge Distillation is a technique where we train a small model to copy the behavior of a big model, so that we can run powerful AI at a low cost.